 |
Hidden Markov Models (HMMs) are a statistical tool commonly used in the field of natural language processing. One specific application of HMMs is in sentence analysis, where the goal is to determine the most likely sequence of hidden states (e.g., part of speech tags) that generated a given sentence. In this article, we will provide a mathematical overview of HMMs and their use in sentence analysis.
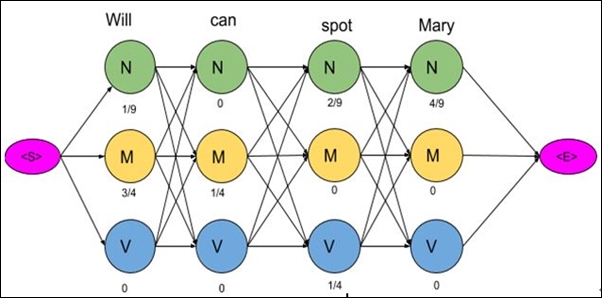
A Hidden Markov Model is defined by three components: an initial probability distribution over hidden states, a set of transition probabilities between hidden states, and a set of observation probabilities given a hidden state. Given a sequence of observations (e.g., a sentence), the goal of HMM inference is to determine the most likely sequence of hidden states that generated the observations. This is typically achieved using the Viterbi algorithm, which computes the maximum likelihood path through the state space.
 |
| https://www.mygreatlearning.com/blog/pos-tagging/ |
To apply HMMs to sentence analysis, we must first define the set of hidden states and observation symbols. In the case of sentence analysis, the hidden states may be part of speech tags (e.g., noun, verb, adjective), while the observation symbols may be words in the sentence. The transition probabilities represent the likelihood of transitioning from one part of speech to another, while the observation probabilities represent the likelihood of observing a specific word given a part of speech.
Training an HMM for sentence analysis requires estimating the parameters of the model (e.g., the transition and observation probabilities) based on a large corpus of annotated data. Once the model has been trained, it can be used to predict the most likely part of the speech sequence for a given sentence by using the Viterbi algorithm.
In conclusion, Hidden Markov Models are a powerful tool for sentence analysis, allowing us to determine the most likely sequence of hidden states (e.g., part of speech tags) that generated a sentence. While the mathematical foundations of HMMs can be challenging to understand, their application in sentence analysis has proven to be extremely effective. With further advancements in machine learning and natural language processing, HMMs will likely continue to play a crucial role in the field.
김강민 강남포스트 학생기자 webmaster@ignnews.kr
<저작권자 © 강남포스트, 무단 전재 및 재배포 금지>
 ‘제3회 역삼1동 어울림 한마당 축제’


