 |
In the realm of swiftly advancing Artificial Intelligence (AI), machines have progressed beyond the point of substituting monotonous tasks, and they can produce novel insights for almost every inquiry. Even though AI systems are capable of producing new knowledge, they are nevertheless fallible, which leads to the creation of incorrect information or what we would refer to as an AI "mistake."
We must first comprehend the fundamental workings of AI to identify the cause of errors. Essentially, AI learns from vast amounts of preexisting data from Big Data by recognizing patterns in the data and using those patterns to generate predictions. This implies that the model may unintentionally replicate the flaws in the data if the data that is used is faulty or biased. Since these types of data are ultimately produced by humans, they may include biases or mistakes that the AI model may pick up on and spread. Furthermore, because data is produced so quickly, the rate of production cannot keep up with the rate at which AI is learning. As a result, the AI might base judgments on outdated information, which might not be reliable.
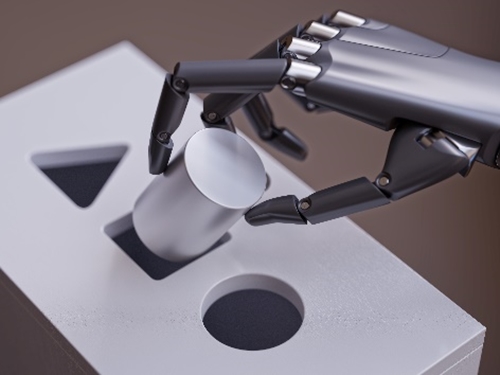 |
| https://www.roboticsbusinessreview.com/events/3-mistakes-robot-companies-make-around-training-ai/ |
The intricacy of the algorithms themselves is another aspect of AI that contributes to errors. As the name suggests, "neural networks" are used to train certain AI models to simulate human thought processes and decision-making. As the AI gathers more data, the system's numerous layers of interrelated information units become increasingly complicated. It's interesting to note that, once trained, AI cannot be understood by laypeople or even developers; this is known as the "black box" property of AI. Like human brains, humans utilize their brains to think and make decisions, but they are not entirely aware of how the brain works. This explains why both complicated systems that measure human intelligence and individuals themselves are prone to error.
Then, how can we address such mistakes? Naturally, we can anticipate the AI to be more accurate the more it is trained. Furthermore, when training AI models, data scientists employ stringent data validation procedures. Moreover, public AI systems are frequently interactive; when a user provides feedback, the system creates a feedback loop so that AI systems can learn from their errors. The AI modifies its models to provide better results in the future if a user reports that the response was inaccurate or unhelpful. Most importantly, as users of AI who don’t have much control over the training data used in the AI, we must learn to discern the flawed data from AI. We must be critical more than before to survive the vast pool of knowledge.
인수호 강남포스트 학생기자 webmaster@ignnews.kr
<저작권자 © 강남포스트, 무단 전재 및 재배포 금지>
 ‘제3회 역삼1동 어울림 한마당 축제’


